AI benchmark explainers
Explainers on AI benchmarks: what SWE-bench, GPQA, ARC-AGI, Humanity’s Last Exam and LMArena measure.
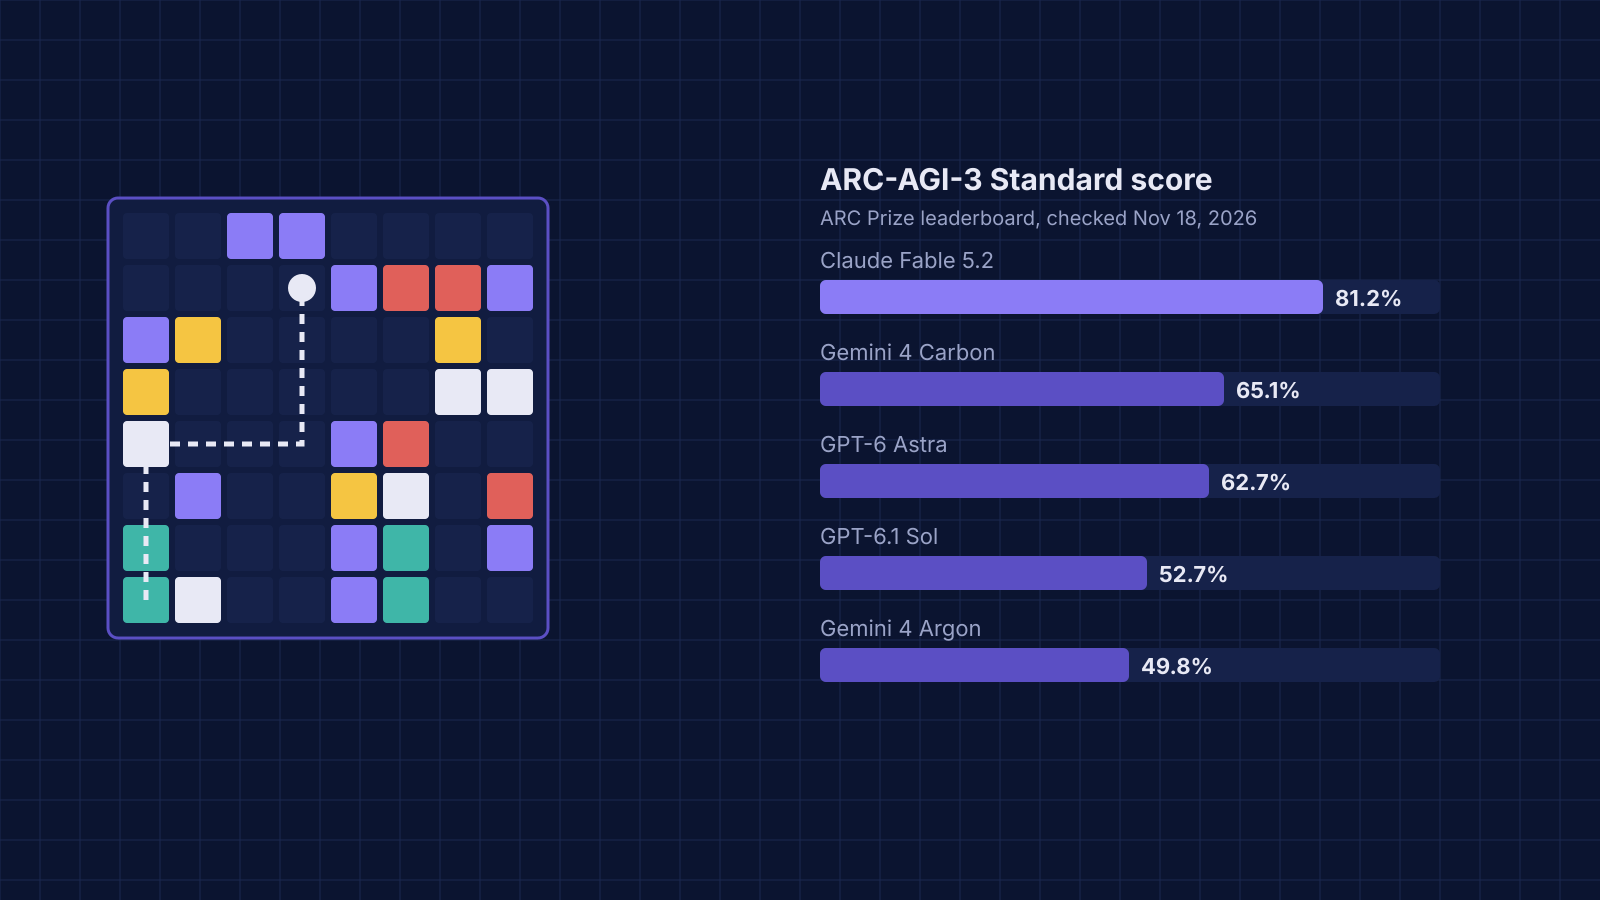
ARC-AGI explained: ARC-AGI-3 scoring, prizes and scores
How ARC-AGI-3 scores agents against human action counts, what ARC Prize 2026 pays, and where frontier models stand.
METR time horizons: what the AI agent benchmark measures
How METR estimates AI task-completion time horizons, what the 50% threshold means and where the benchmark's limits lie.
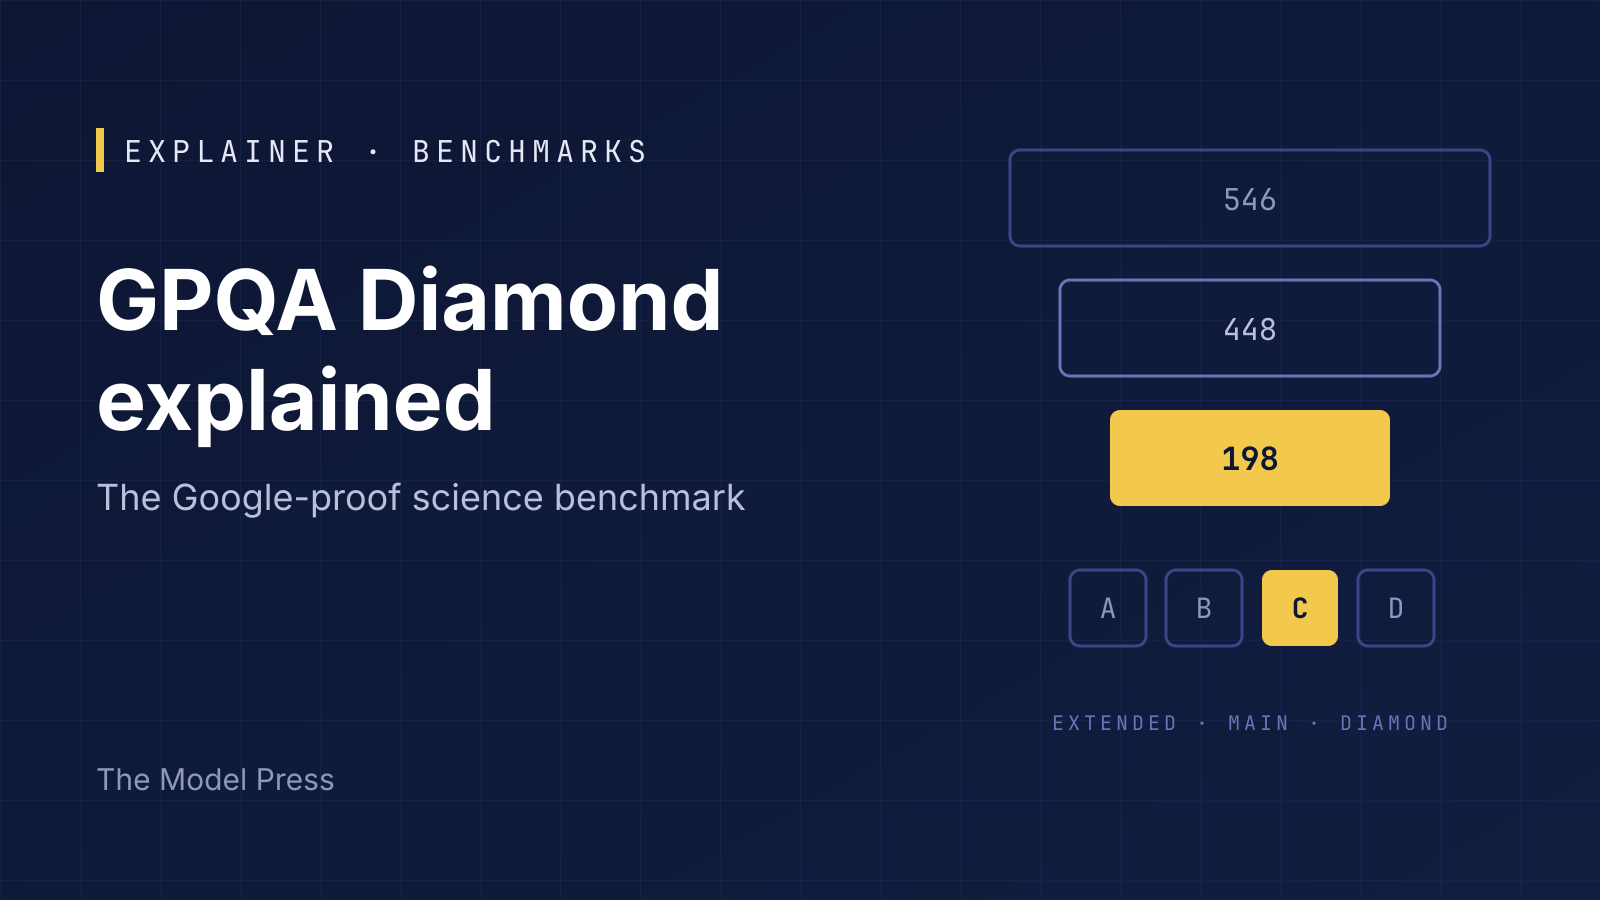
GPQA Diamond explained: the Google-proof science benchmark
How GPQA's 198 Diamond questions were chosen, what a GPQA score means and the limits its authors list.
HumanEval benchmark explained: problems, pass@k and limits
HumanEval tests generated Python functions against hidden tests. Its score is narrower than real coding work.
SWE-bench Explained: Issues, Patches and Test Results
How SWE-bench turns GitHub issues into tested patches, and why benchmark versions affect score comparisons.
These pages explain what each benchmark tests, how it is run and scored, and what it misses, from the maintainers’ own documentation, so a published score can be read in context. Scores reported by labs and maintainers are collected on the LLM leaderboard, and new results are in AI benchmark news.