Latest
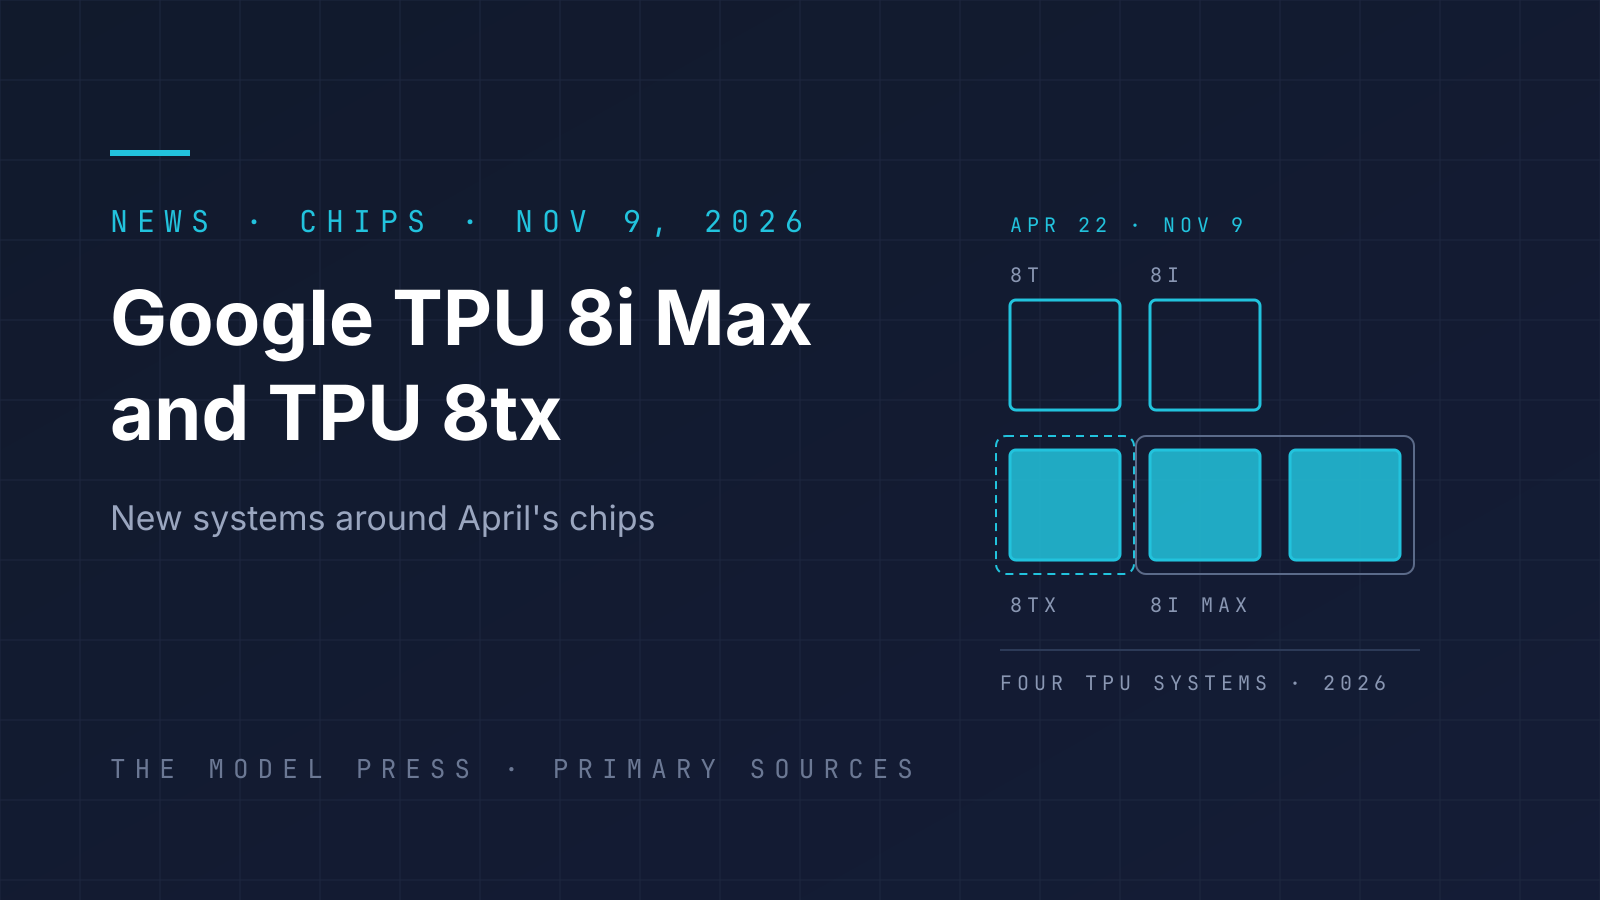
Google TPU 8i Max and TPU 8tx, announced November 9, 2026: what Google published
TPU 8i Max is two TPU 8i chips on one package; TPU 8tx pairs TPU 8t silicon with AMD EPYC hosts.
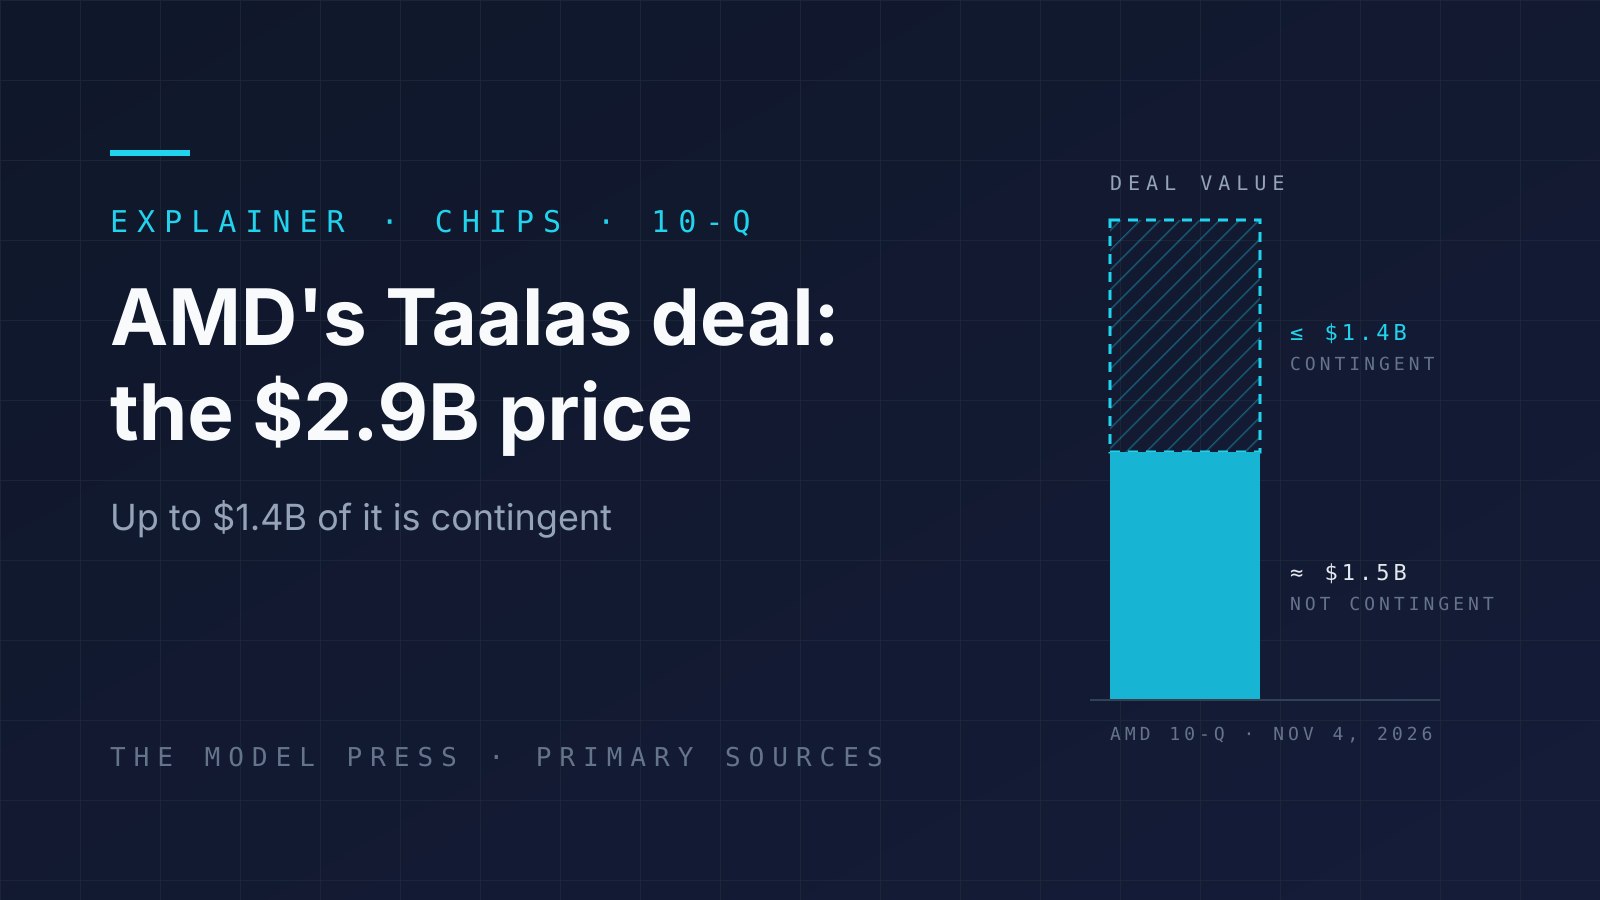
AMD Taalas acquisition: the $2.9 billion price and what Taalas builds
AMD's 10-Q puts the Taalas deal at about $2.9 billion, up to $1.4 billion contingent, plus the HC1 chip's specs.
SambaNova SN50 heads to Supermicro inference racks on November 3, 2026
SambaNova SN50 specs, and Supermicro's November 3, 2026 plan for 10,000 SN50 chips paired with Nvidia GPUs.
AI inference vs training compute: what's the difference
Training builds a model and inference runs it, and the two stress AI hardware in different ways.
AMD Helios racks running at Meta, AMD says on October 27, 2026
AMD said on October 27, 2026 that its first Helios racks are installed and in testing at Meta, ahead of a wider rollout.
Huawei Ascend: China's AI chips explained
Huawei Ascend AI chips from the 910 series to the 950, 960, 970 and 980, as Huawei described them at Huawei Connect.
Intel Gaudi explained: specs and where it stands
Intel Gaudi explained: Gaudi 3 specs from Intel's own paper, where to get it, and Intel's next AI chip.
HBM suppliers: SK hynix, Samsung and Micron in the HBM race
SK hynix, Samsung and Micron all say they ship HBM4 in volume as of October 2026; here is where each supplier stands.
TSMC and AI chips: why so many accelerators run through it
TSMC makes and packages the silicon behind Nvidia GPUs, Broadcom XPUs and Intel Gaudi 3: nodes, CoWoS and Arizona.
Broadcom AI chips: custom XPUs and who designs them
Broadcom's AI chips are custom accelerators (XPUs) built for Google, Meta, OpenAI and others.
Google Cloud A5X with Vera Rubin NVL72 announced October 21, 2026
Google Cloud A5X instances on Vera Rubin NVL72, announced October 21, 2026, reach general availability next month.
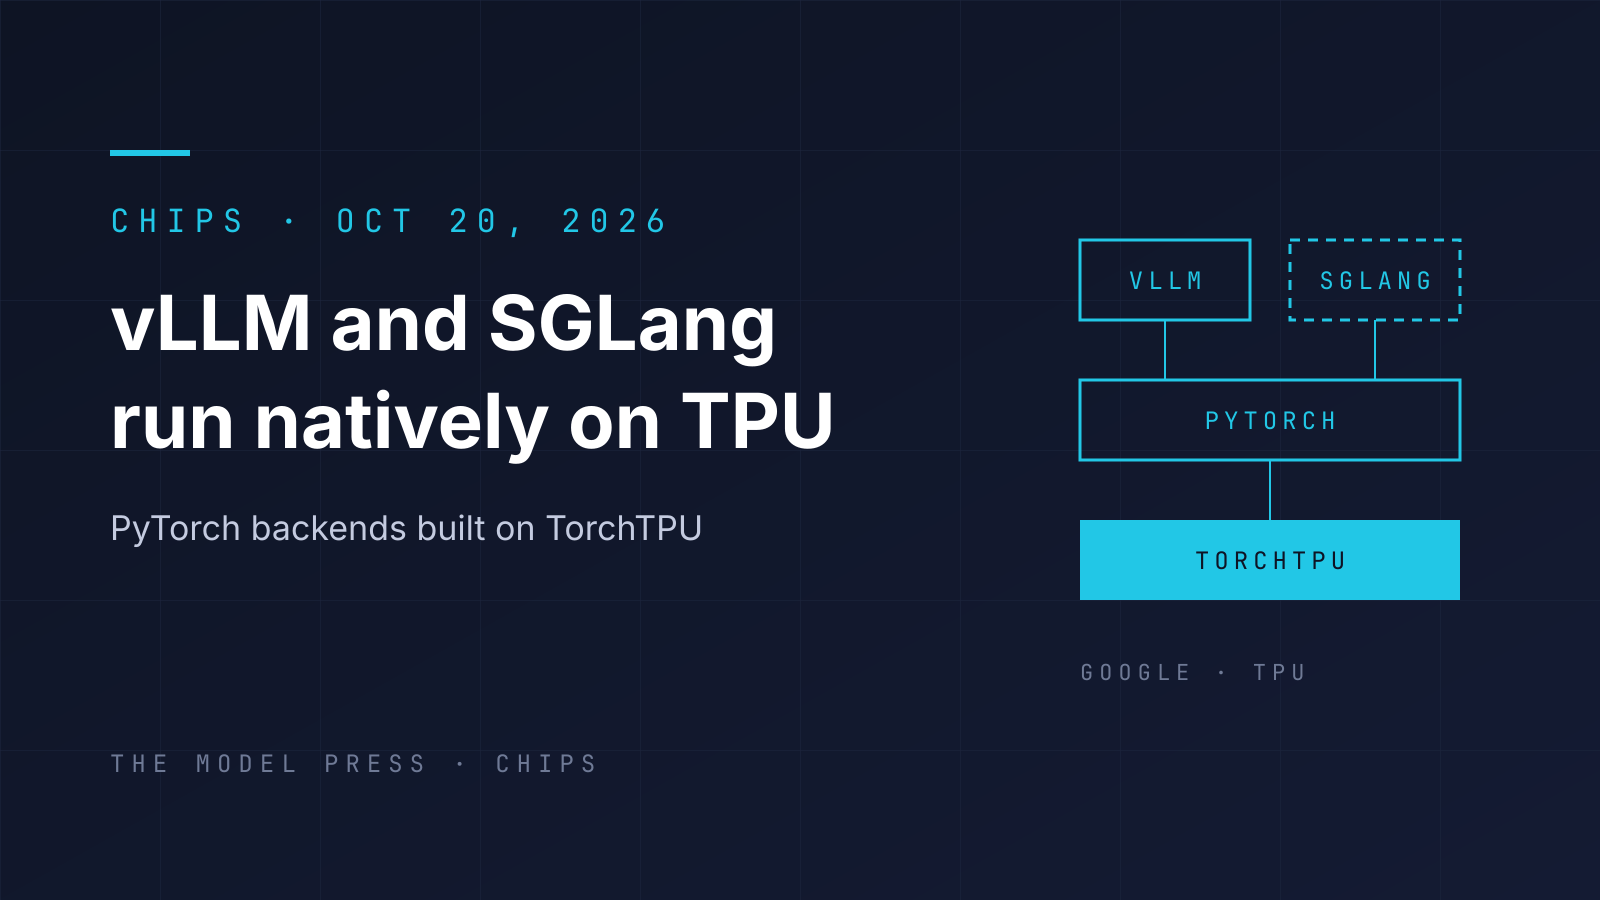
vLLM and SGLang on TPU: Google's PyTorch engines, October 20, 2026
Google's new vLLM and SGLang engines run natively on TPU through TorchTPU, launched October 20, 2026.
AI chip export controls: what the US rules restrict
US AI chip export rules as of November 5, 2026: TPP limits worked through, the China and UAE rules, the affiliates rule.
Nvidia's data-center GPU roadmap, Hopper to Rubin
Nvidia went from Hopper through Blackwell and Blackwell Ultra to Vera Rubin in four years; here is each generation.
Groq AI and its LPU: what the inference chip does
Groq built the LPU, an inference chip that keeps model weights in on-chip SRAM, and runs it as the GroqCloud service.
Cerebras Systems: the wafer-scale chip and its business
Cerebras Systems builds AI processors from a whole silicon wafer and sells both systems and inference cloud access.
AWS Trainium: what it is and which models train on it
AWS Trainium is Amazon's own AI chip, rented through EC2 Trn2 and Trn3 instances and UltraServers.
Ultra Ethernet 1.1 adds scale-up links and collectives
Ultra Ethernet 1.1 adds a local accelerator profile, in-network collectives and new congestion controls.
Google TPU: generations and who can use them
Google's TPUs run Gemini and are rented through Google Cloud, from v5e to Ironwood and the announced TPU 8t and 8i.
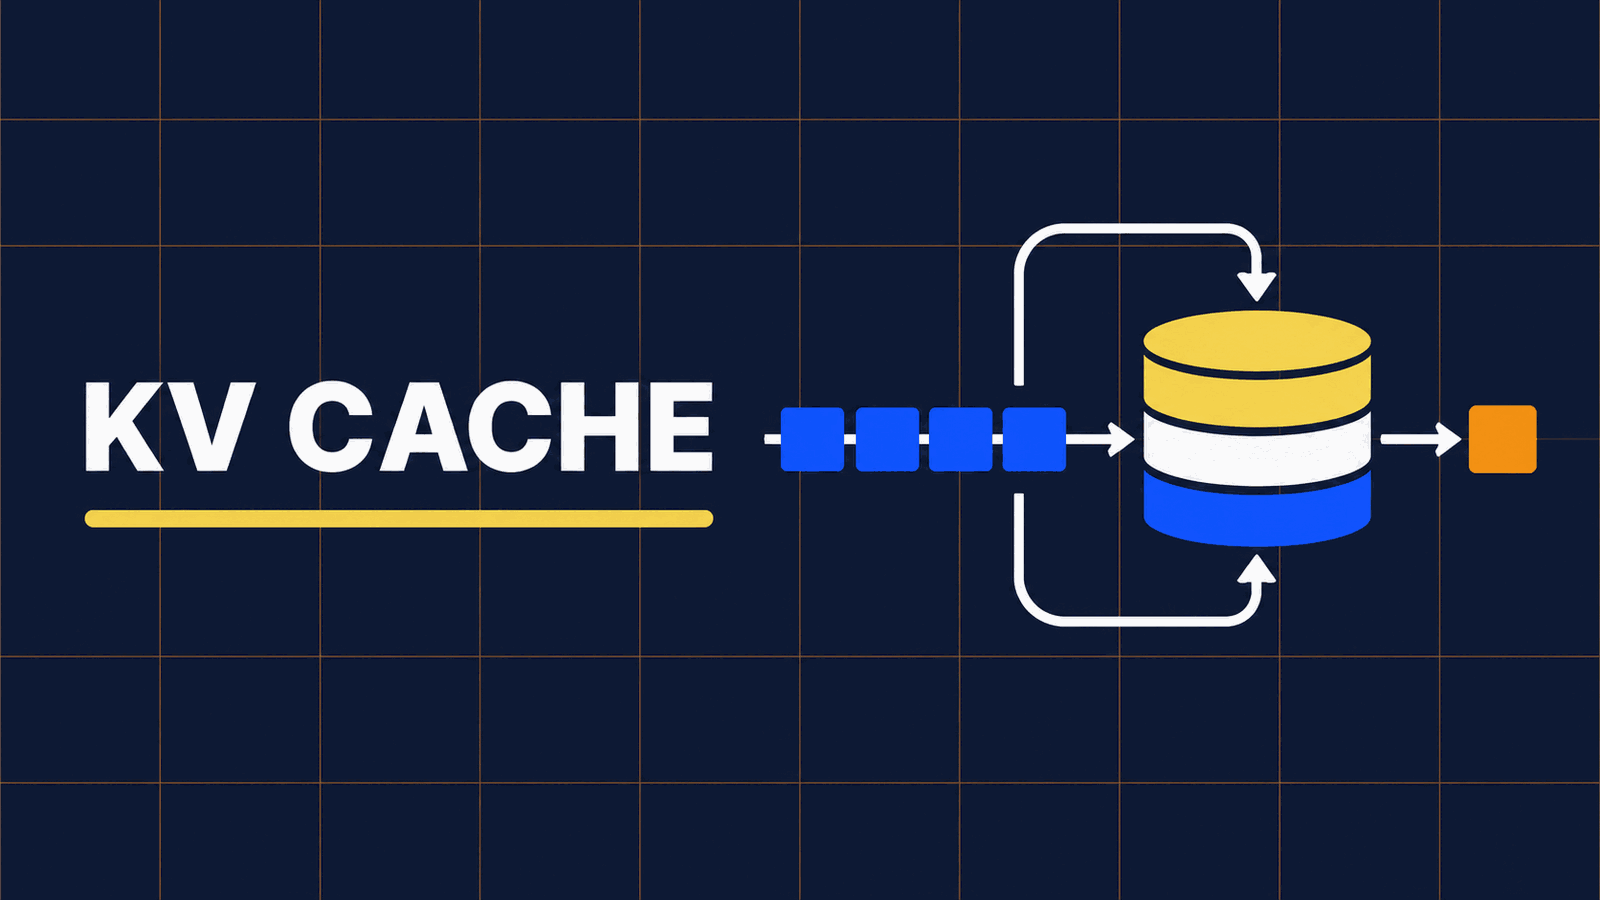
KV cache explained: how it speeds up AI inference
A KV cache reuses attention keys and values during generation, saving compute while using more accelerator memory.
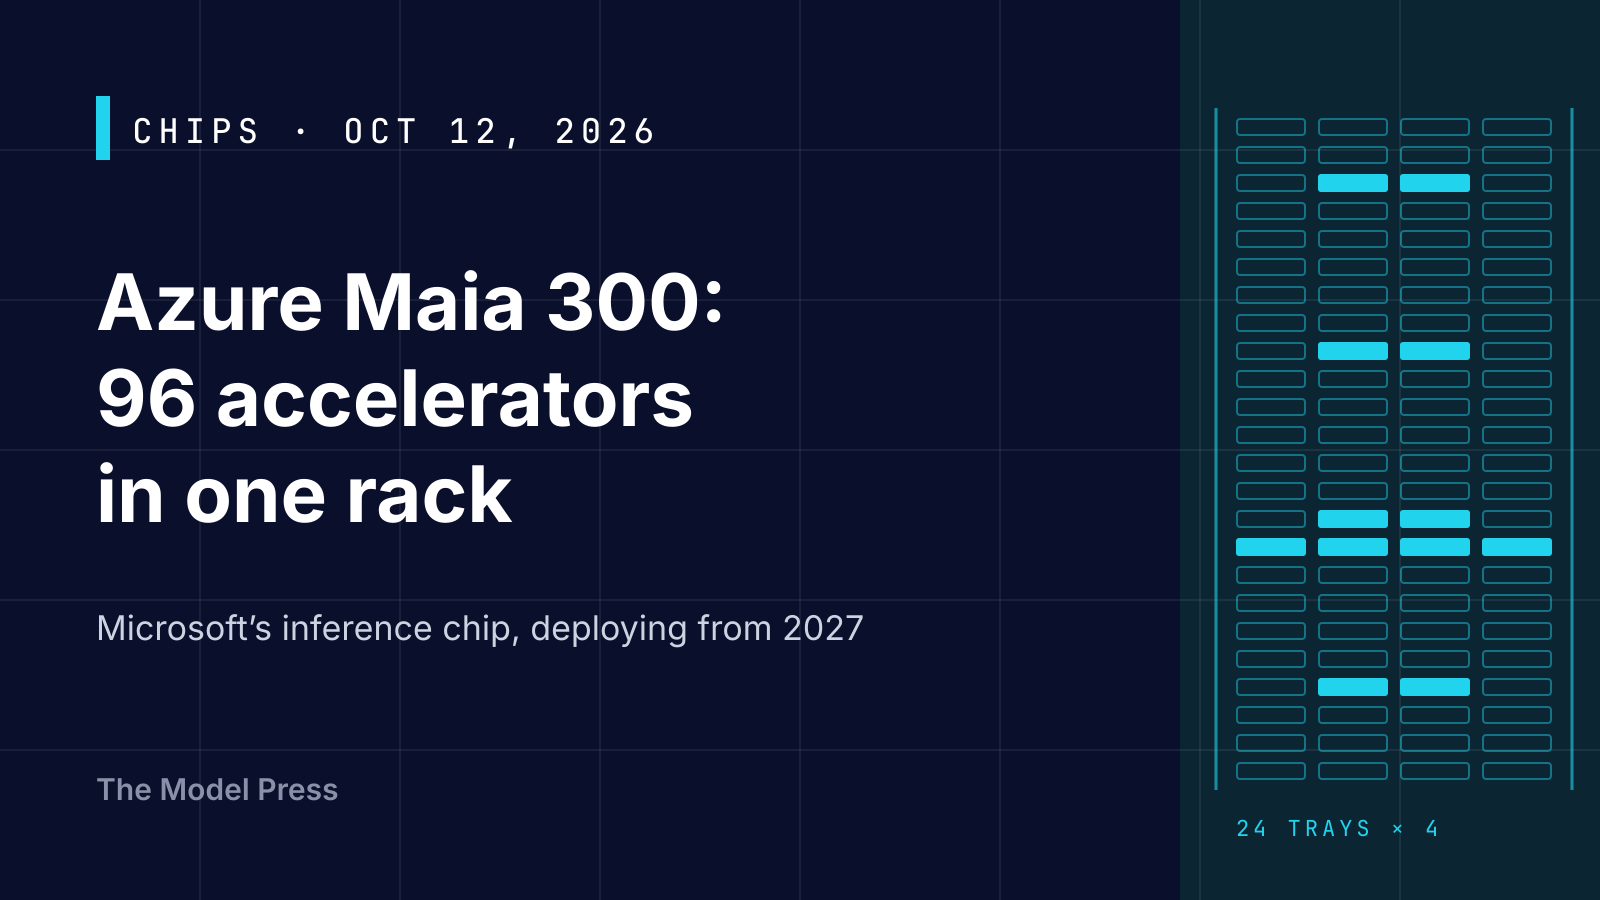
Microsoft unveils Azure Maia 300 on October 12, 2026: 96-chip racks
Microsoft unveiled Azure Maia 300 on October 12, 2026: 288 GB of HBM4 per chip, 96 chips per 167 kW rack.
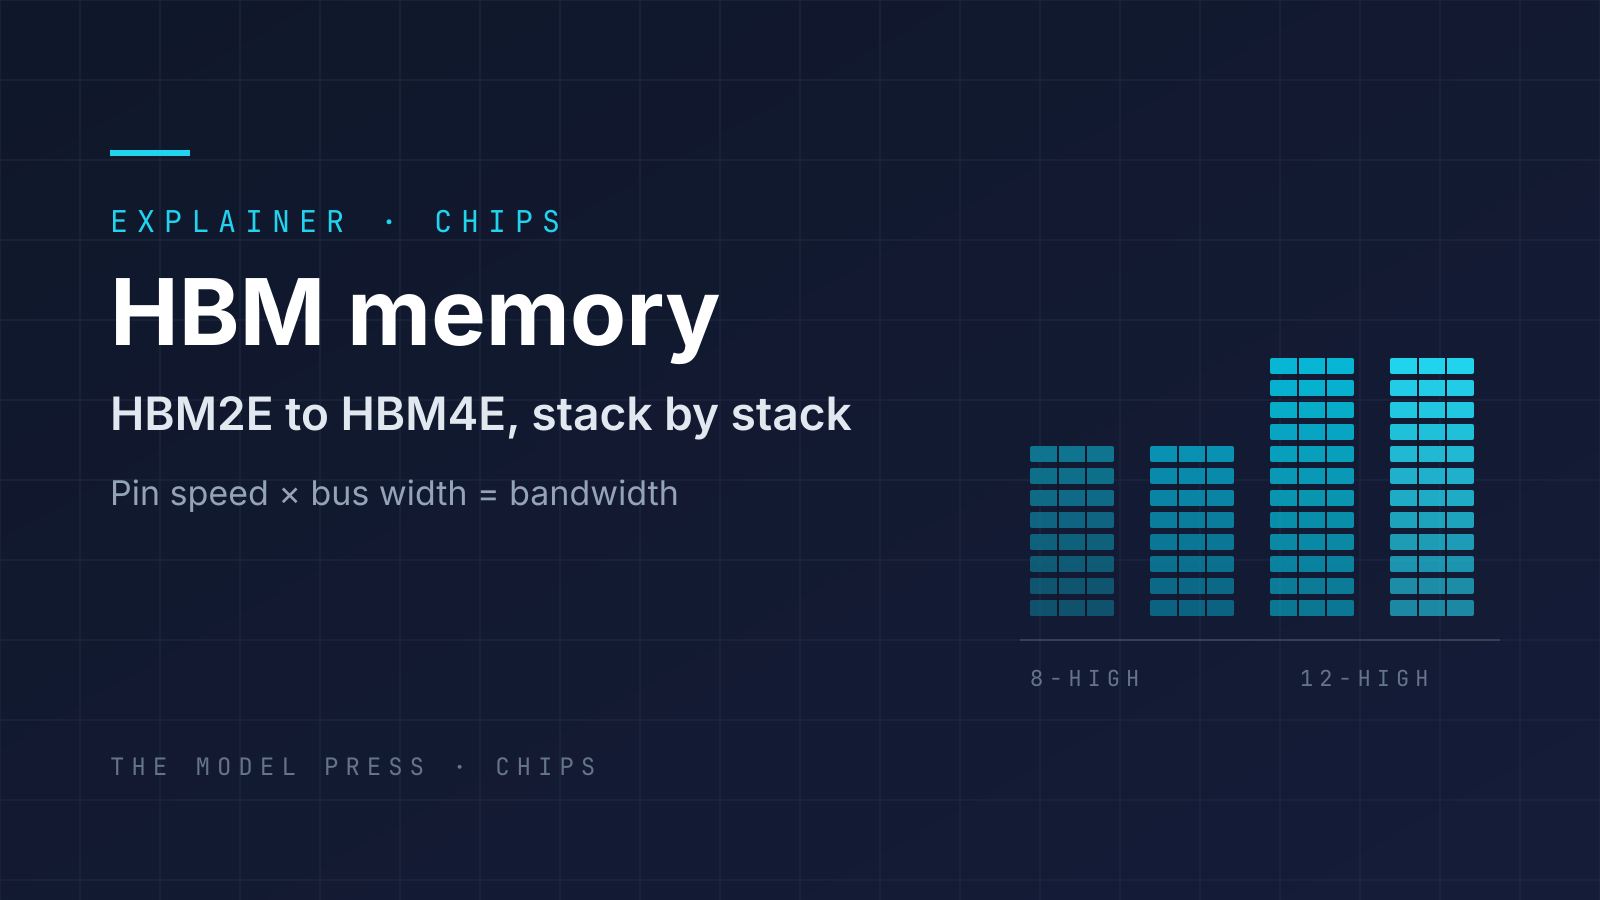
HBM memory explained: HBM2E, HBM3, HBM3E and HBM4 compared
HBM2E, HBM3, HBM3E, HBM4 and HBM4E compared by width, pin speed, bandwidth and capacity per stack.
AMD Instinct MI355X: specs and how it compares
The AMD Instinct MI355X is AMD's CDNA 4 accelerator with 288 GB of HBM3E at 8 TB/s and 1,400 W board power.
NVIDIA Opens RTX Spark Preorders for Windows AI PCs
Laptops are due October 16 and compact desktops in November; DGX Station for Windows remains a preview.